PyHealth Tutorials

Learn PyHealth in Colab

Nine hands-on notebooks for PyHealth 2.1, from your first clinical prediction model to calibration, interpretability, clinical text and contributing. Every notebook runs on a free Colab runtime with synthetic or public data, so no credentials are needed.

What's new in 2.1

Already using PyHealth? Three short notebooks, about 10 minutes each, show every 2.1 change on runnable examples: the pitfall it fixes, the new API, and how to read the output. See also the release notes.

1

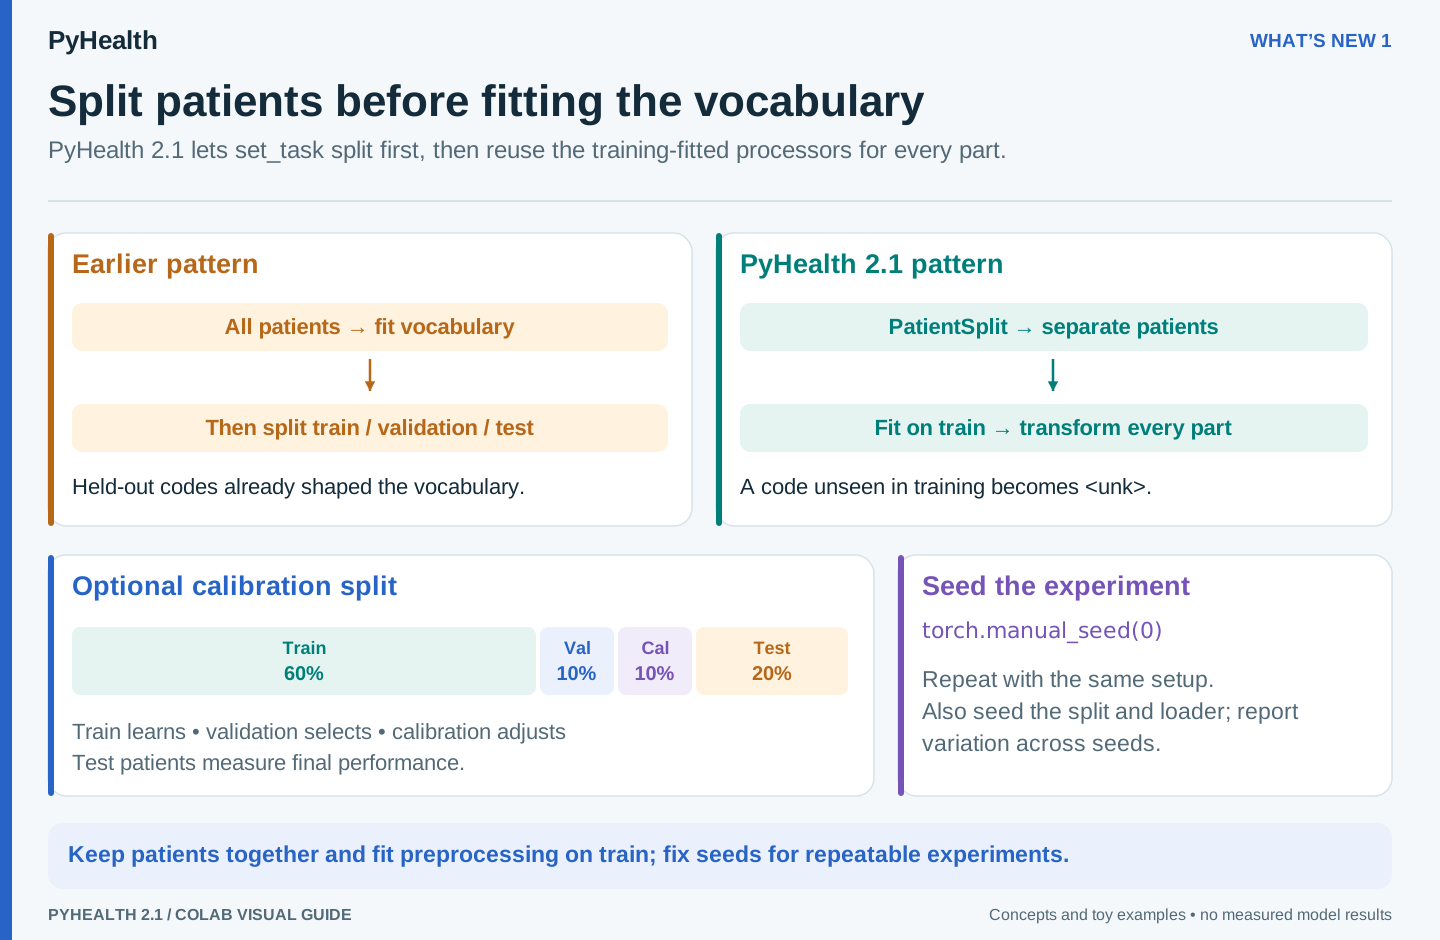
Splits you can trust, runs you can repeat

  • set_task(task, split=PatientSplit(...)): why fitting vocabularies on all patients leaks test information, measured on real numbers
  • Four-way splits with a calibration set
  • Reproducible training from torch.manual_seed alone, and seeded loaders
  • The one action item for 2.0 users: rebuild caches made with more than 10 workers
about 10 minutes on a free Colab CPU runtime · Before this: the Quickstart, or any PyHealth 2.0 experience

Visual guide: Split patients before fitting the vocabularyVisual guide · click to enlarge
Open in Colab →
2

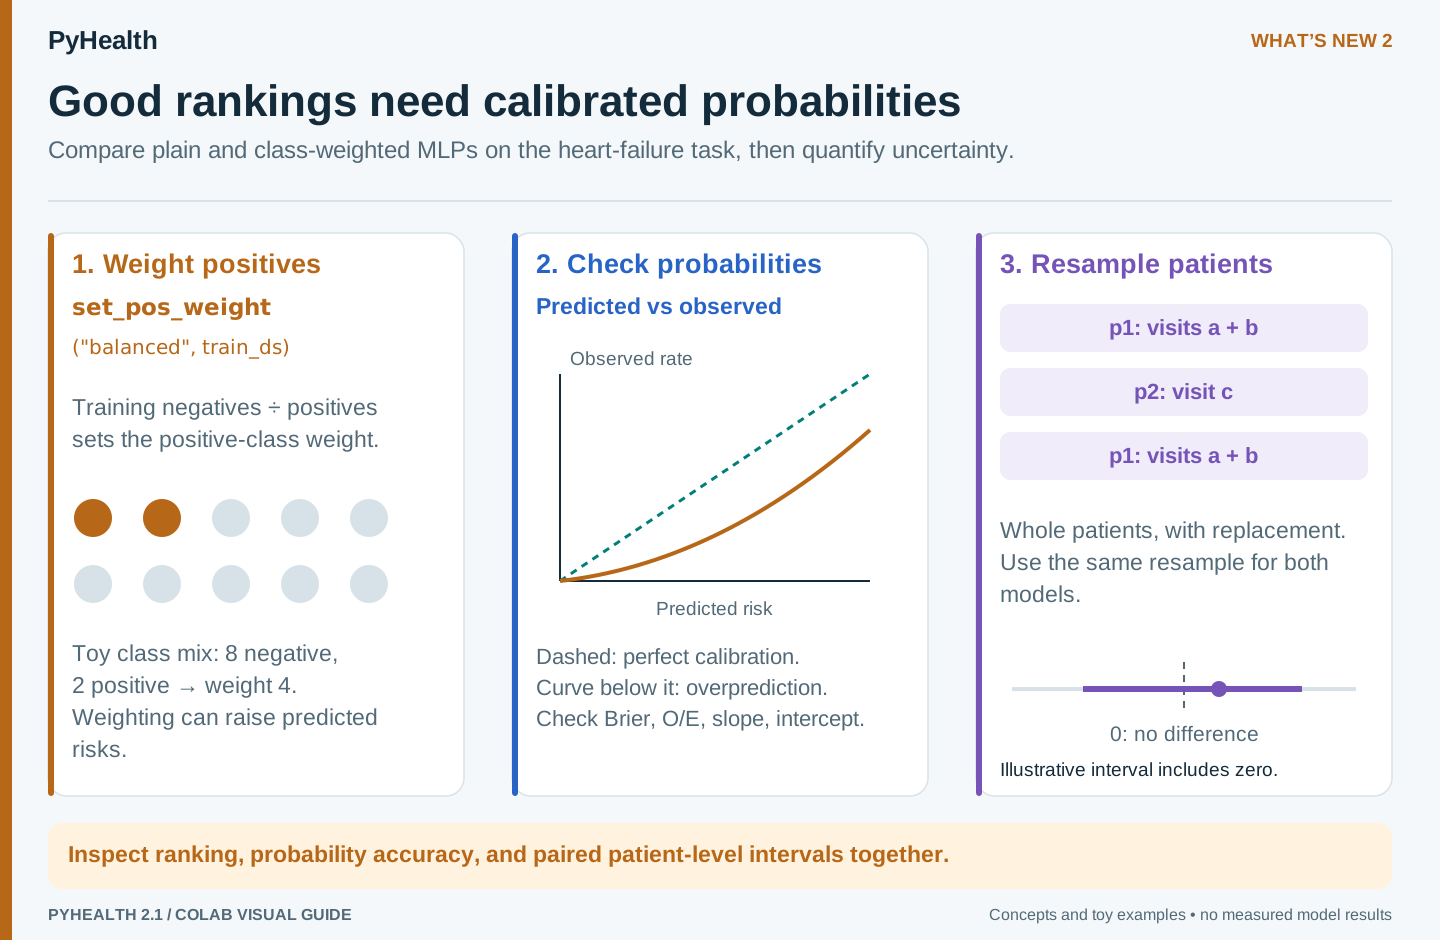
Calibration, confidence intervals and imbalanced outcomes

  • set_pos_weight, including "balanced", and what weighting does to calibration
  • Brier score, observed/expected ratio, calibration slope and intercept
  • Patient-level bootstrap_ci and paired_bootstrap_diff: is model A really better than B?

about 10 minutes on a free Colab CPU runtime · Before this: the Quickstart, or any PyHealth 2.0 experience

Visual guide: Good rankings need calibrated probabilitiesVisual guide · click to enlarge
Open in Colab →
3

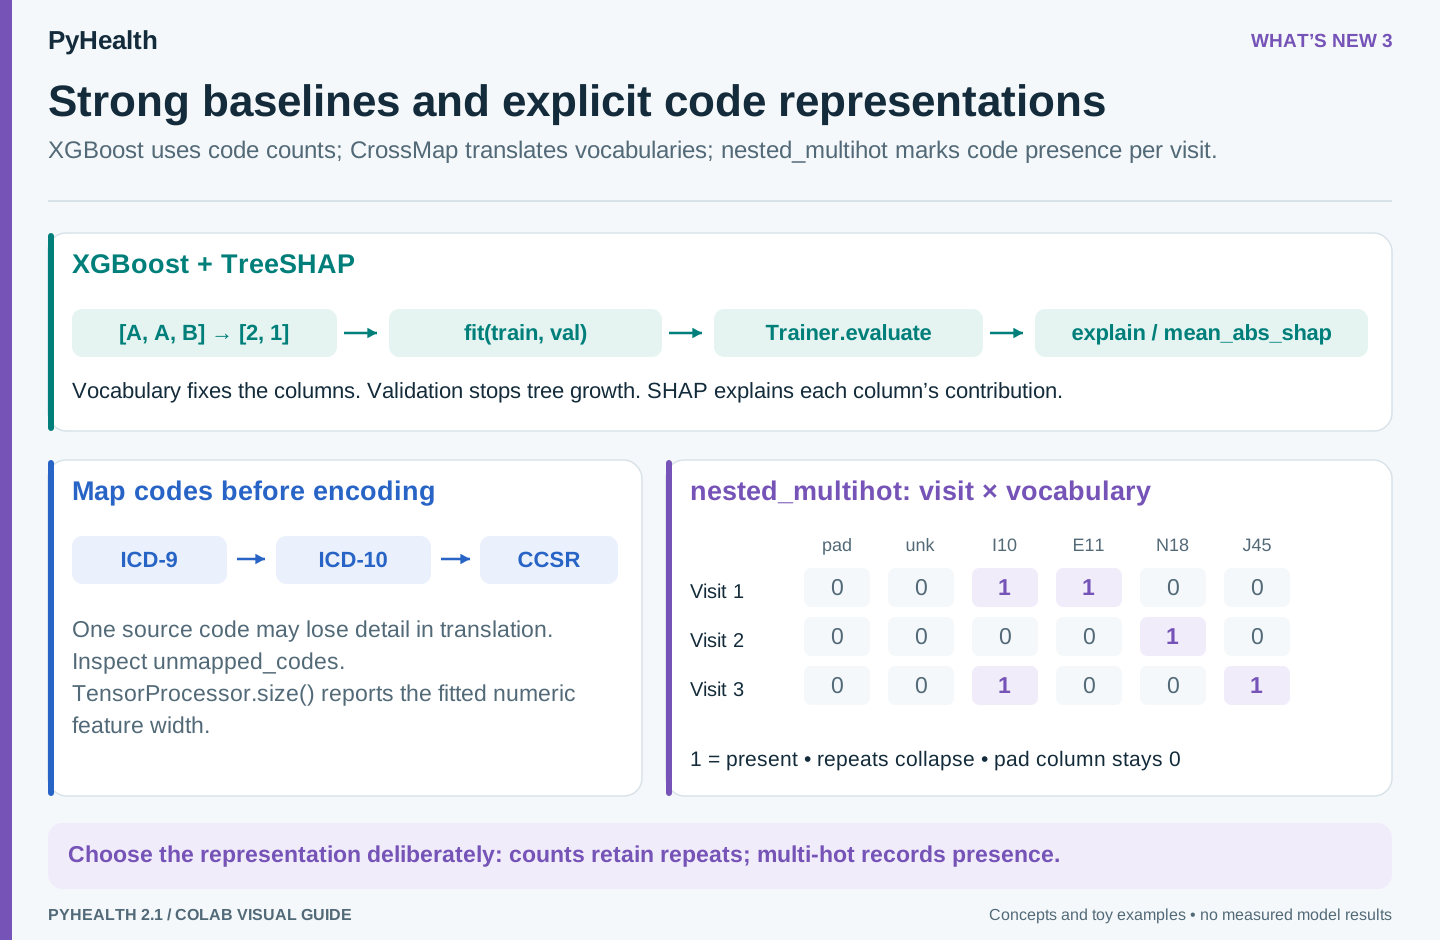
XGBoost with exact explanations, medical-code translation and new processors

  • XGBoostModel: a strong baseline in four lines that works with Trainer.evaluate
  • Exact TreeSHAP explanations with mean_abs_shap and explain
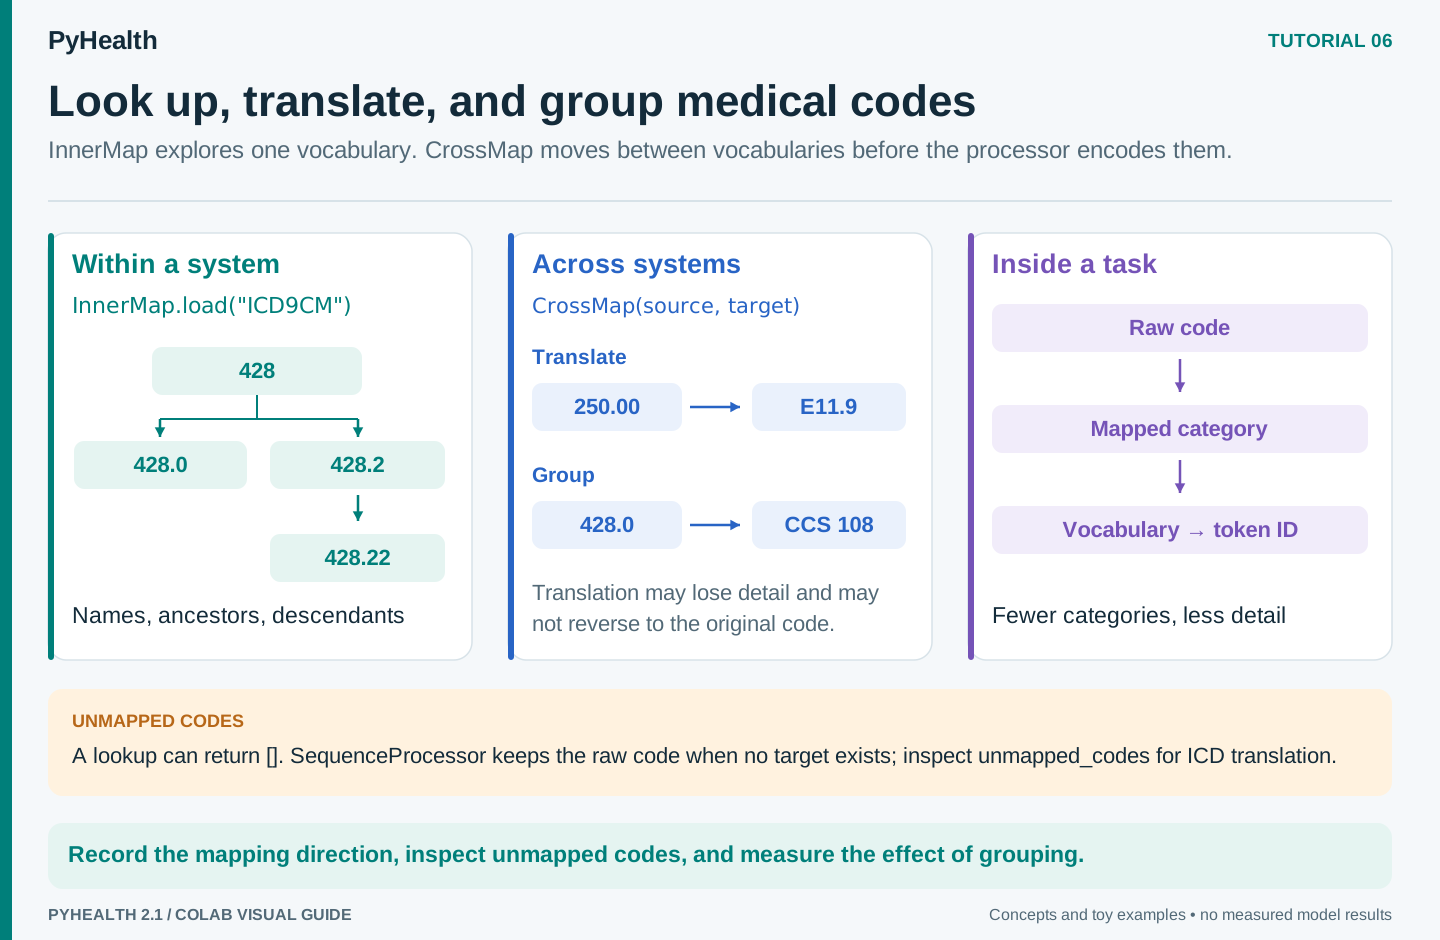
  • ICD-9 ↔ ICD-10 translation and CCSR groupings in CrossMap, with unmapped codes reported
  • The compact nested_multihot encoding and TensorProcessor.size()

about 10 minutes on a free Colab CPU runtime · Before this: the Quickstart, or any PyHealth 2.0 experience

Visual guide: Strong baselines and explicit code representationsVisual guide · click to enlarge
Open in Colab →

The full series

Open a notebook and choose Runtime > Run all. The first cell installs pyhealth==2.1.0. Each tutorial lists what it assumes, so you can also jump straight to the topic you need. Tested end to end on Colab with PyHealth 2.1.0.

00

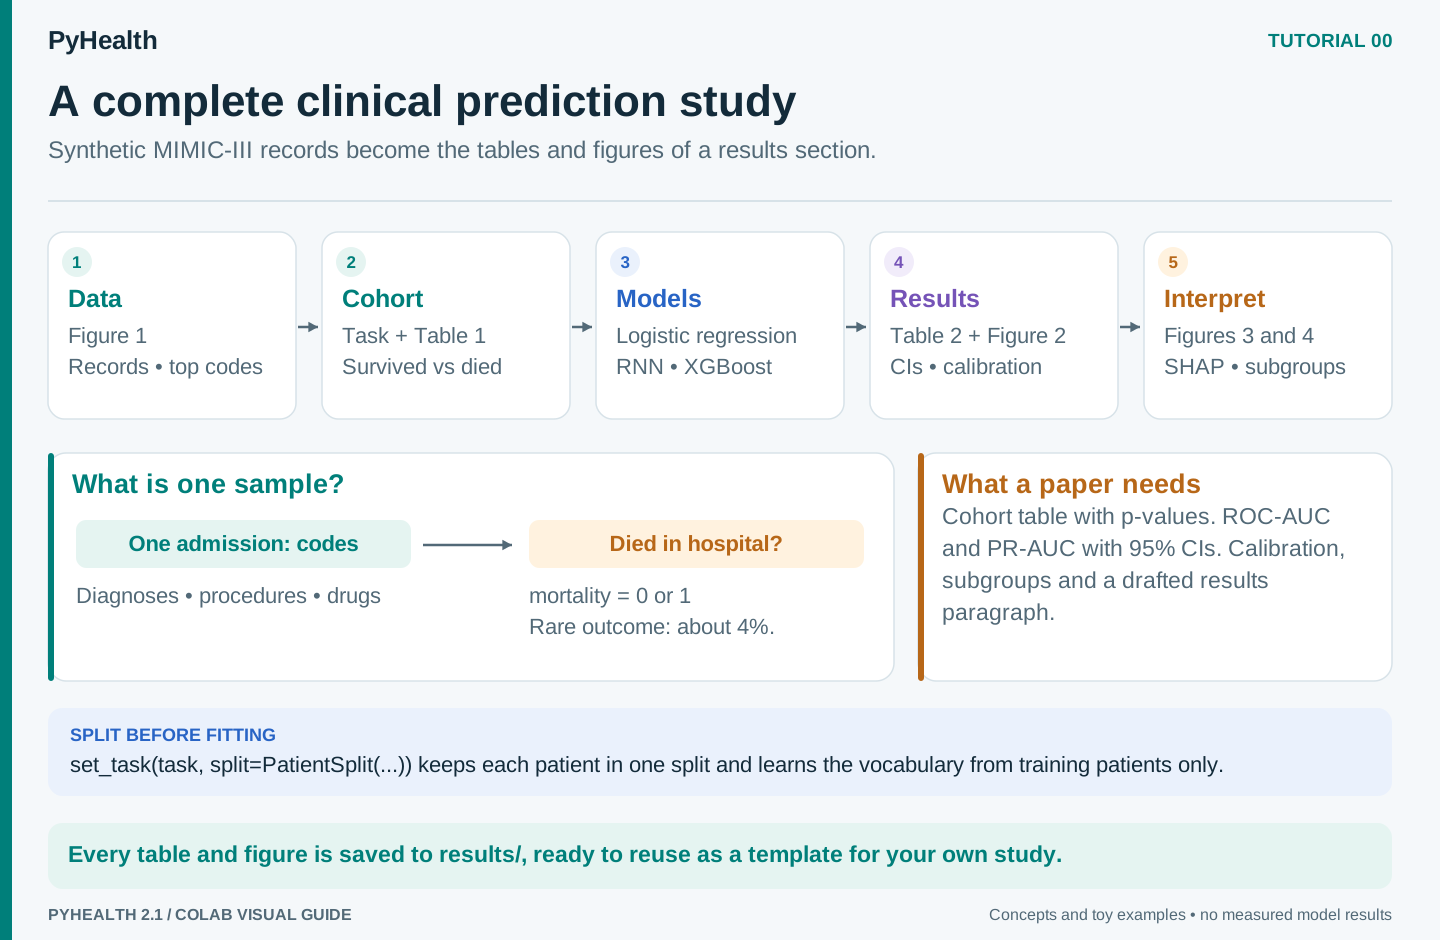
Quickstart: a complete clinical prediction study

  • A full study in one notebook: predict in-hospital death from an admission's diagnosis, procedure and drug codes, with a leakage-free patient split
  • See the data and the cohort: a patient's record, the most common codes, and a Table 1 of survivors and deaths with p-values
  • Compare logistic regression, an RNN and XGBoost: ROC-AUC and PR-AUC with 95% confidence intervals, calibration, and a top-10% risk review
  • Explain and check the best model with SHAP and subgroup results, then export every table and figure, plus a drafted results paragraph, to use as a template

about 10 minutes on a free Colab T4 GPU, the runtime it opens with (about 15 on a CPU) · Before this: nothing. This is the place to start

Visual guide: A complete clinical prediction studyVisual guide · click to enlarge
Open in Colab →
01

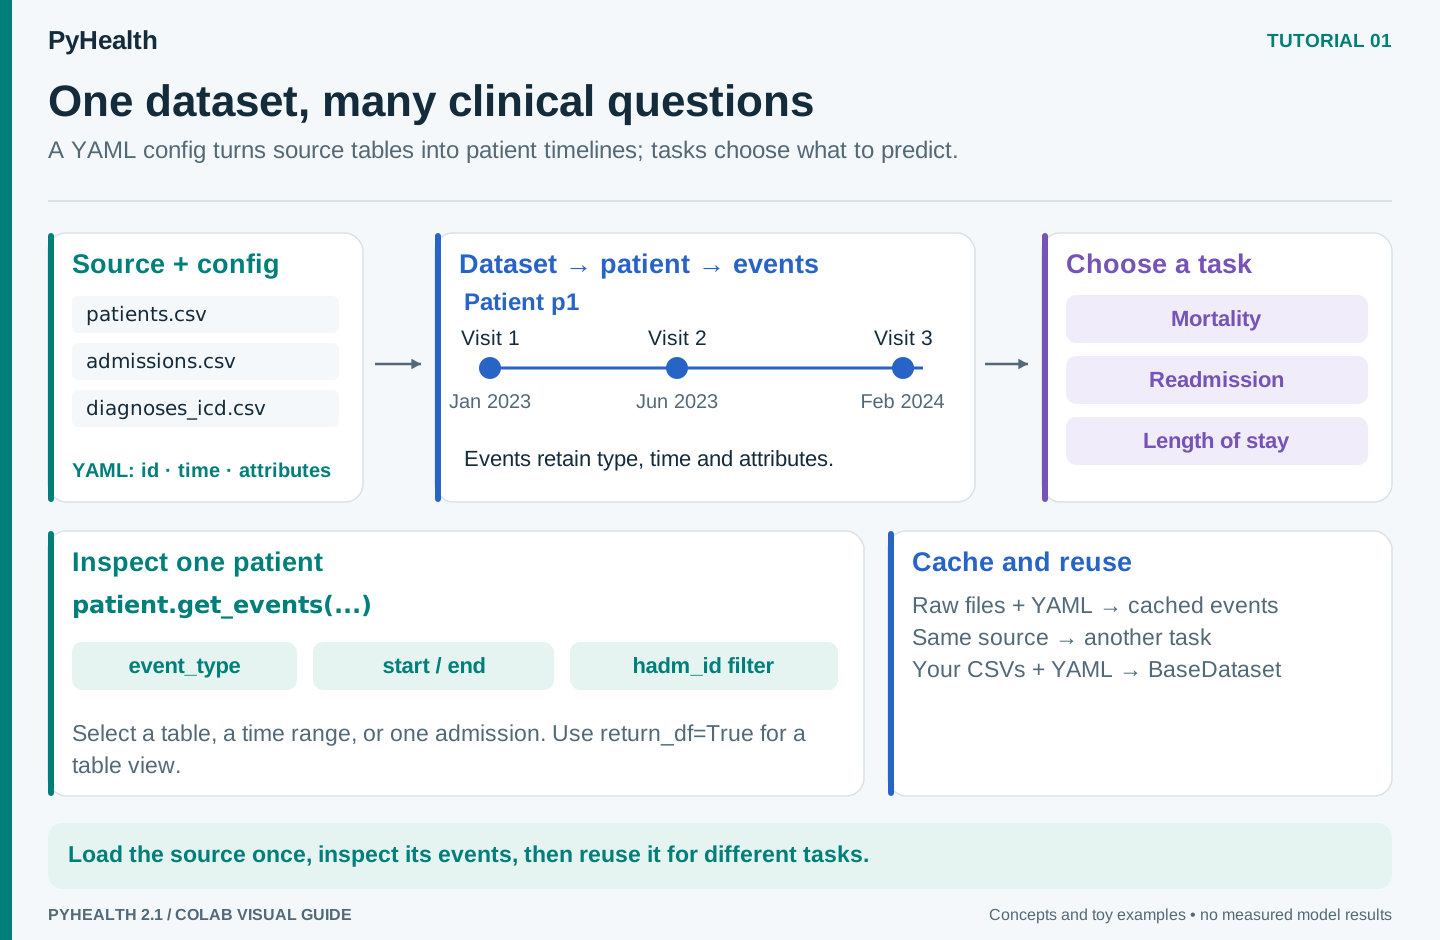
Datasets: patients, events and your own data

  • The difference between a dataset and a task, and why PyHealth keeps them apart
  • How to explore patients and their events, filter by type, time or admission
  • What the YAML config does, and how caching works
  • How to load your own CSV files with a short config, no new class needed

about 20 minutes on a free Colab CPU runtime · Before this: Tutorial 00 (Quickstart) is helpful but not required

Visual guide: One dataset, many clinical questionsVisual guide · click to enlarge
Open in Colab →
02

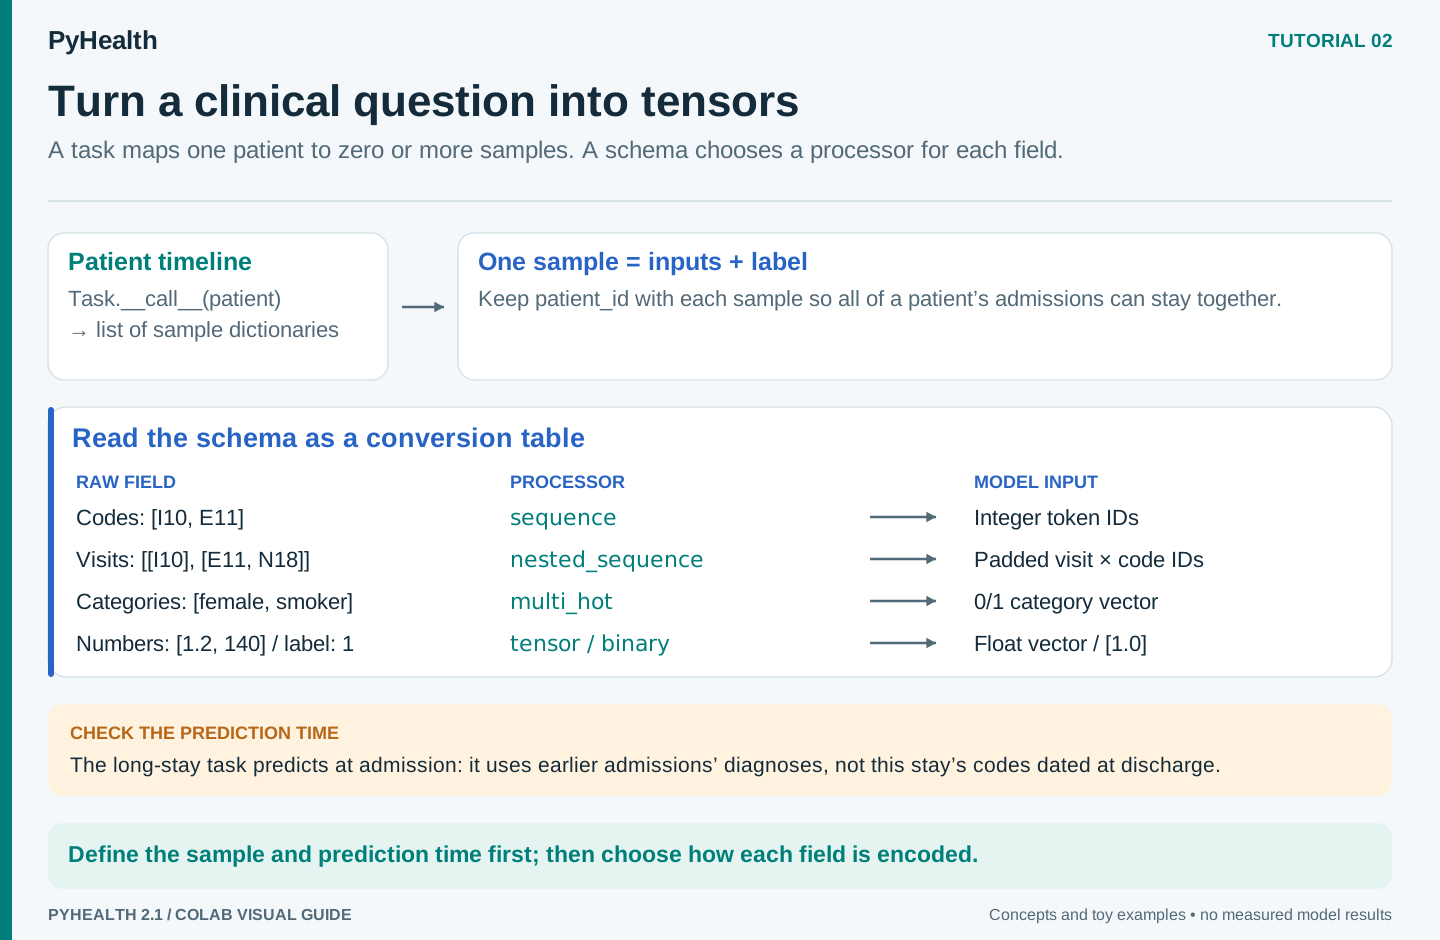
Tasks and processors: from patients to model-ready samples

  • What a task is: a function from one patient to a list of samples
  • How input and output schemas pick a processor for each field
  • What each common processor produces (sequence, nested sequence, multi-hot, tensor, labels)
  • How to write your own task, filter patients early, and use it with any model

about 25 minutes on a free Colab CPU runtime · Before this: Tutorial 01 (Datasets)

Visual guide: Turn a clinical question into tensorsVisual guide · click to enlarge
Open in Colab →
03

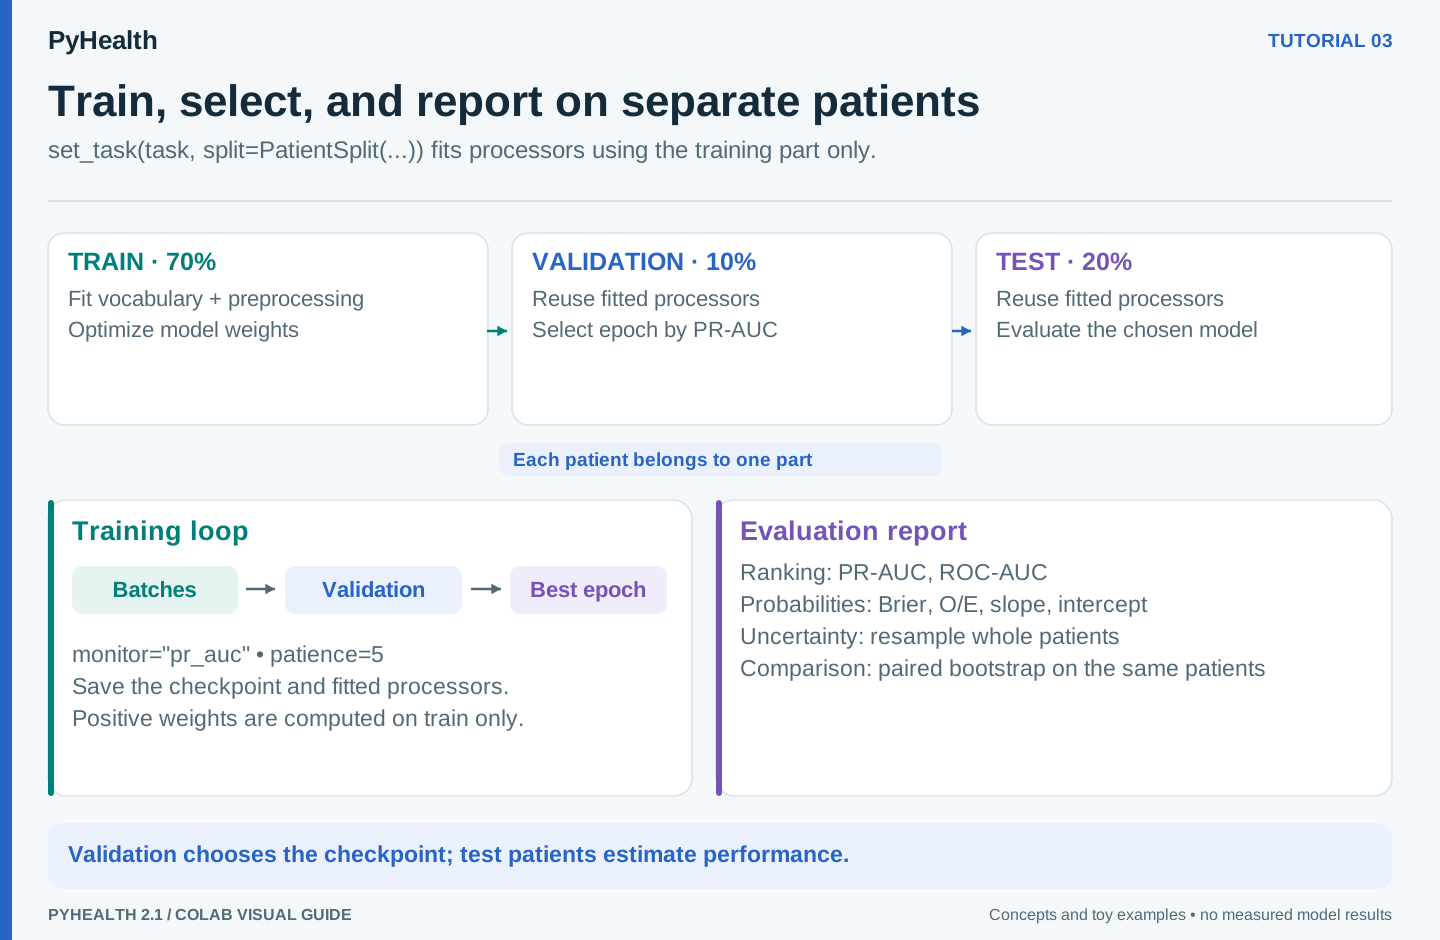
Training and evaluating models properly

  • How to split so that nothing about the test patients leaks into training
  • How to control training: epochs, early stopping, learning rate, checkpoints
  • How to handle a rare outcome with a positive-class weight, and what it costs
  • How to report discrimination and calibration with patient-level confidence intervals

about 25 minutes on a free Colab CPU runtime · Before this: Tutorials 00 and 02

Visual guide: Train, select, and report on separate patientsVisual guide · click to enlarge
Open in Colab →
04

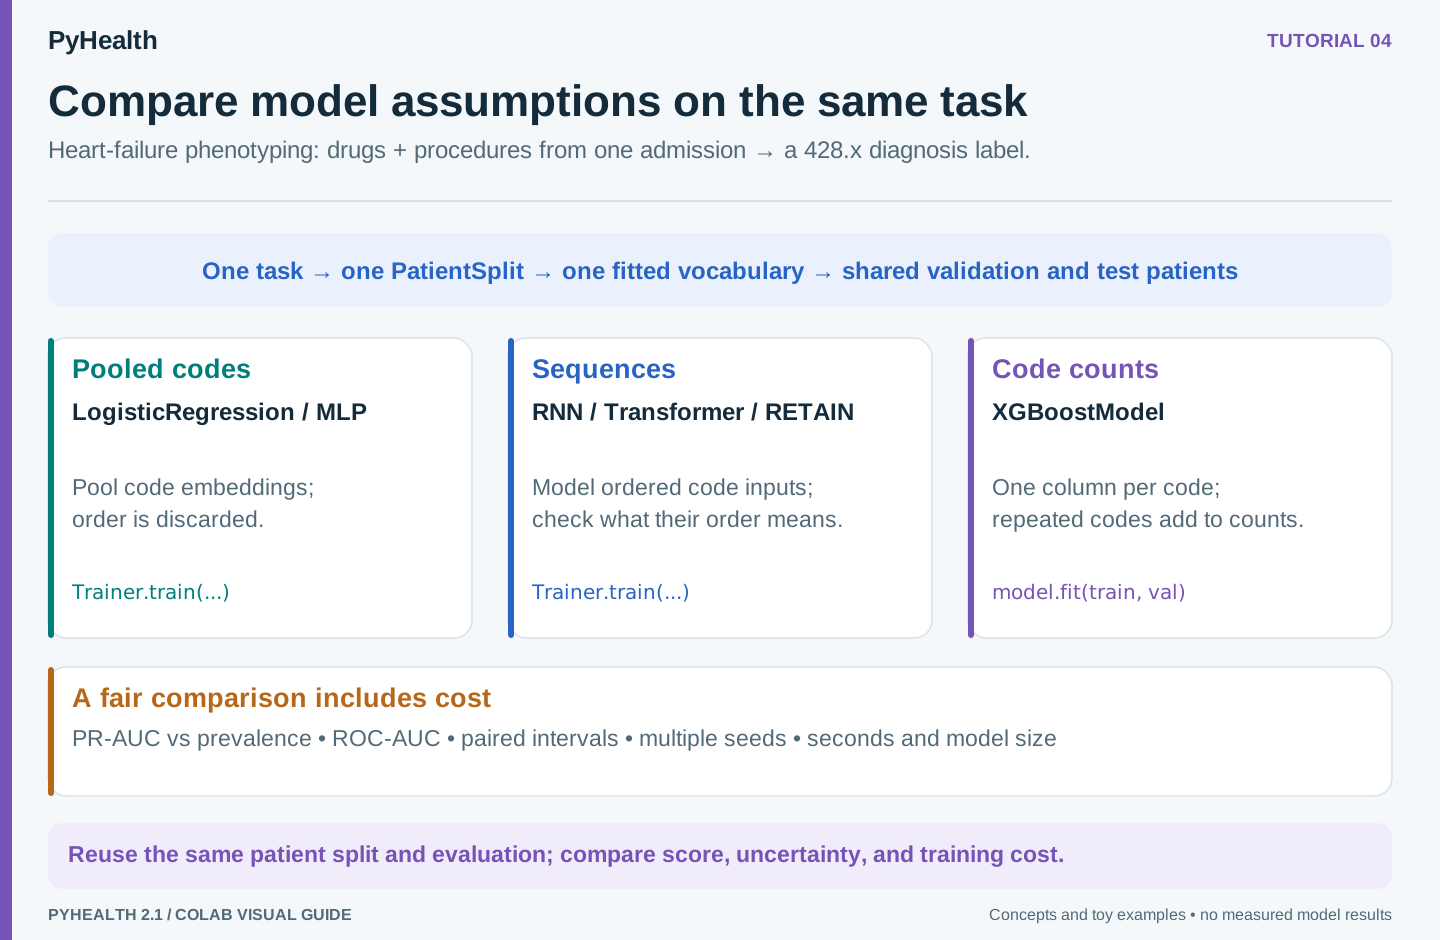
Choosing a model: from logistic regression to XGBoost

  • What the main PyHealth models assume about the data, and when to pick each
  • How to compare several models fairly on the same patients
  • How to add a gradient-boosted tree baseline (XGBoost) to a PyHealth benchmark

about 12 minutes on a T4 GPU, the runtime it opens with (about 15 on a CPU, without the three sequence models) · Before this: Tutorial 03

Visual guide: Compare model assumptions on the same taskVisual guide · click to enlarge
Open in Colab →
05

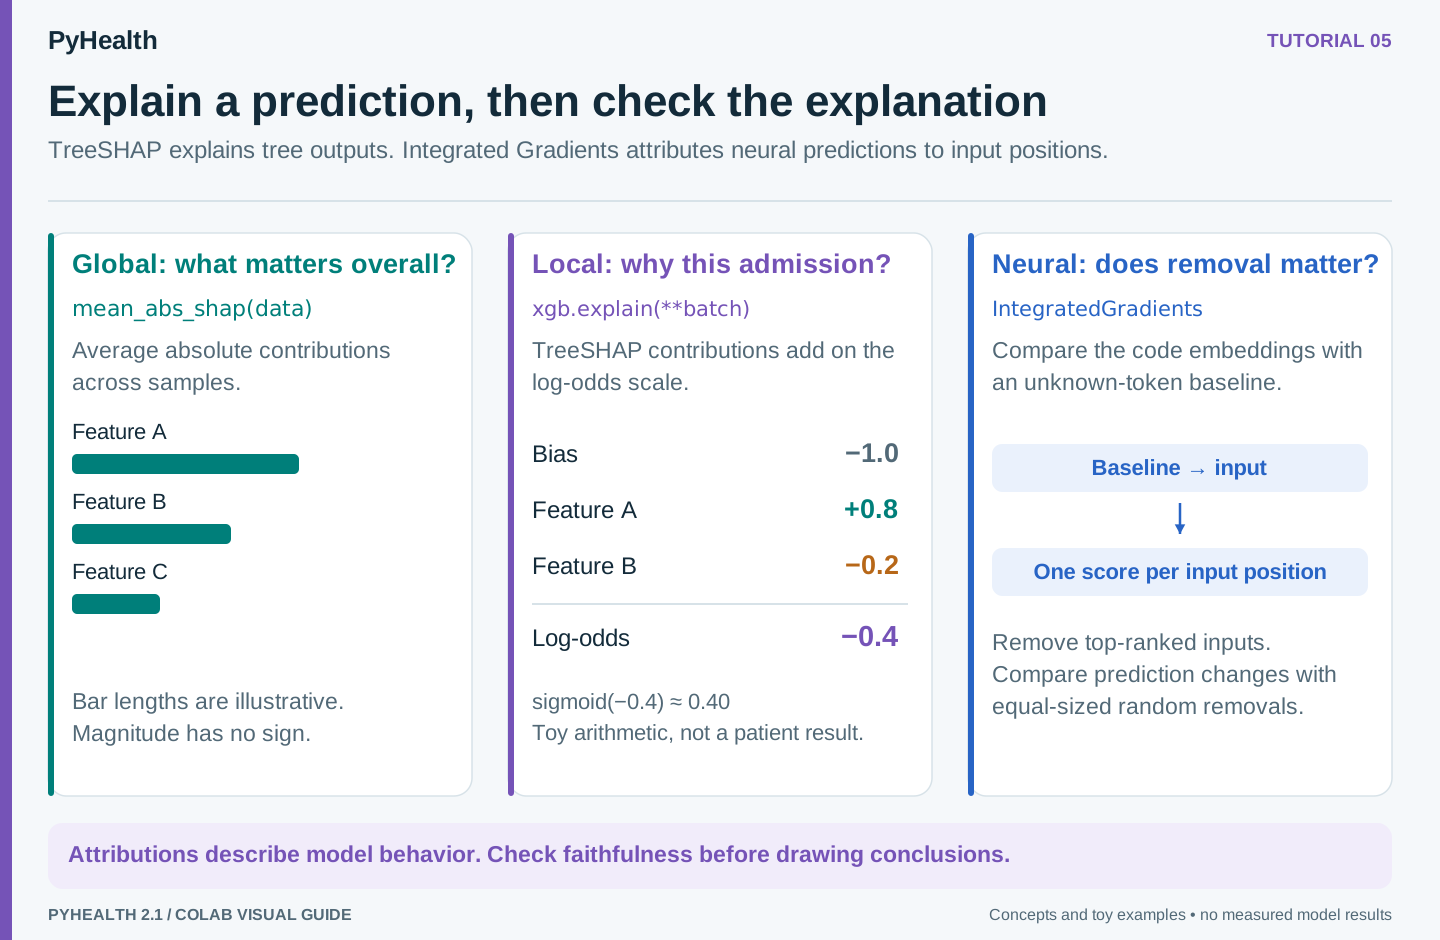
Interpreting predictions

  • Which inputs drive a model overall (global importance) and for one patient (local explanation)
  • Exact TreeSHAP for XGBoost, and Integrated Gradients for neural models
  • How to check whether an explanation is faithful to the model, not just plausible

about 20 minutes on a free Colab CPU runtime · Before this: Tutorial 04 (we reuse its heart-failure task)

Visual guide: Explain a prediction, then check the explanationVisual guide · click to enlarge
Open in Colab →
06

Medical codes: lookups, mappings and groupers

  • What the common code systems are (ICD-9, ICD-10, CCS, ATC, NDC) and how they relate
  • How to look up a code's name, parents and children
  • How to translate between ICD-9 and ICD-10 and group codes into broader categories
  • How to use a grouping inside a task to shrink the vocabulary a model must learn

about 15 minutes on a free Colab CPU runtime · Before this: Tutorial 02 (processors and vocabularies)

Visual guide: Look up, translate, and group medical codesVisual guide · click to enlarge
Open in Colab →
07

Clinical text: classification and medical coding

  • How to fine-tune a Hugging Face language model on clinical notes with PyHealth
  • How to read a label distribution before modelling, and what a model's correct answers look like
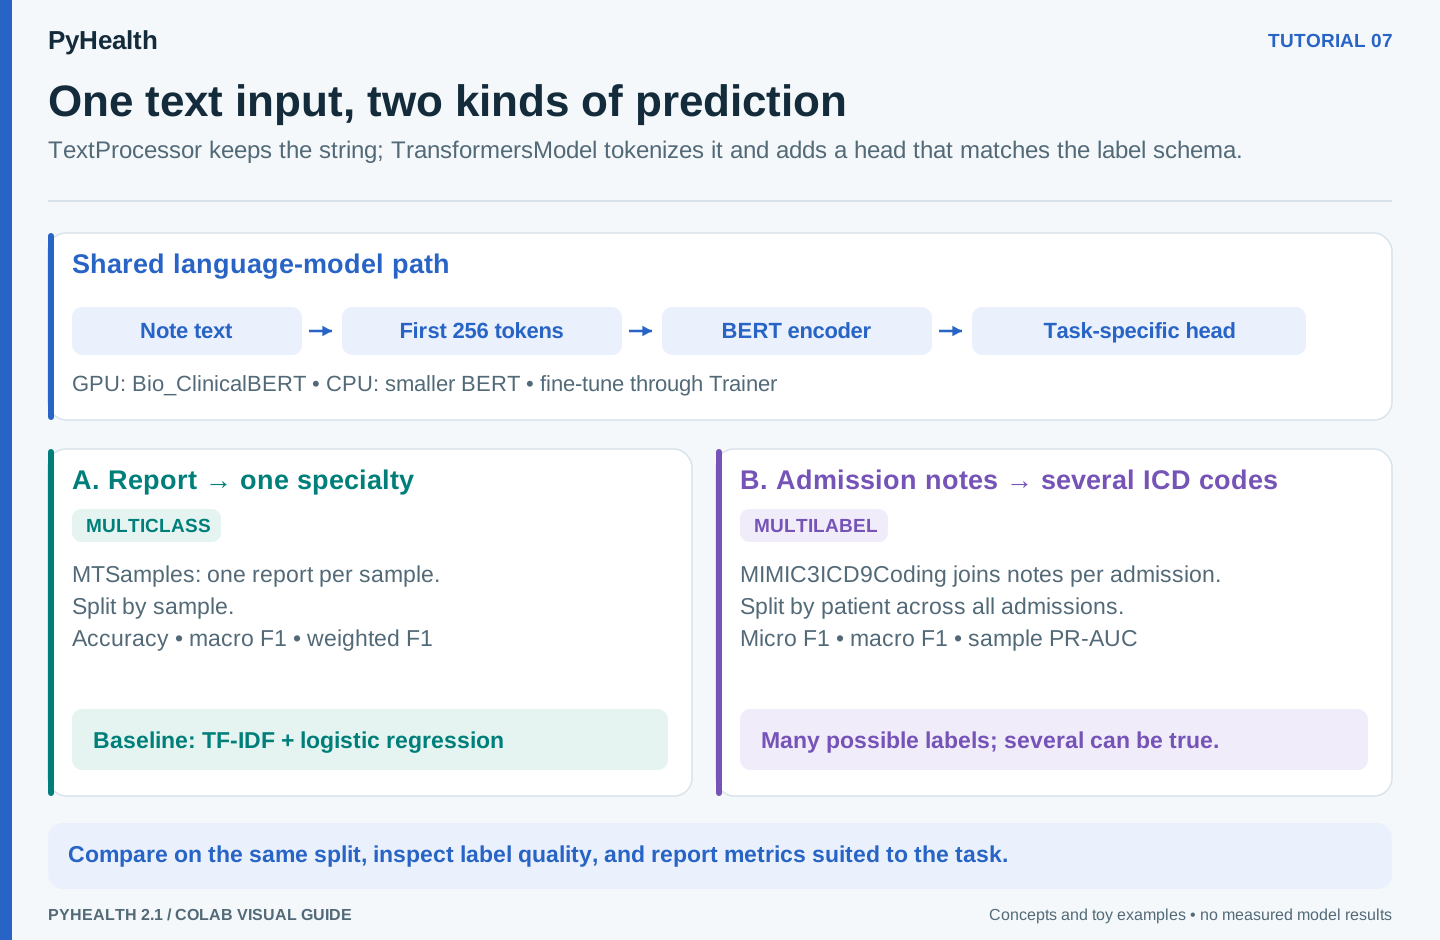
  • Multiclass text classification: which specialty wrote this report?
  • Multilabel medical coding: which ICD codes does this note support?
  • Why a simple TF-IDF baseline belongs next to every language model

about 15 minutes on a T4 GPU, the runtime it opens with (about 25 on a CPU, with a smaller model) · Before this: Tutorials 00 and 02

Visual guide: One text input, two kinds of predictionVisual guide · click to enlarge
Open in Colab →
08

Contributing a dataset or task to PyHealth

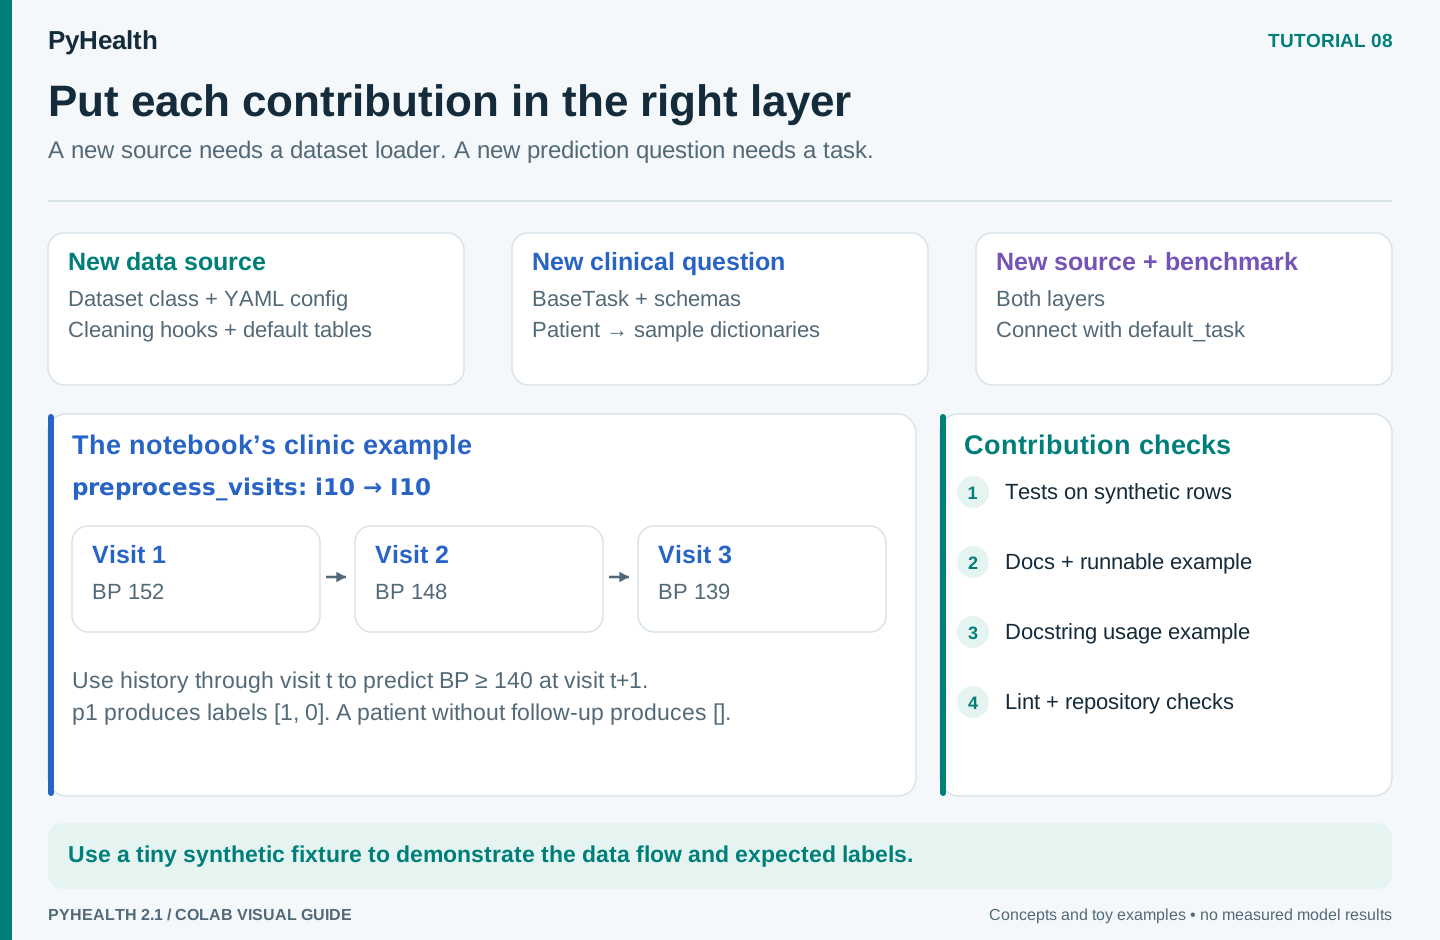
  • Whether your idea is a dataset, a task, or both
  • How a dataset class is built: config, default tables, per-table preprocessing, a default task
  • How to handle data that is not a table (files on disk)
  • How to test it with tiny synthetic data, and what a PR needs to pass review

about 25 minutes on a free Colab CPU runtime · Before this: Tutorials 01 and 02

Visual guide: Put each contribution in the right layerVisual guide · click to enlarge
Open in Colab →